A proxy scraper collects proxy server addresses, usually IP addresses and ports, from published lists, websites, or APIs. That is different from a web scraper that uses a proxy to collect product rows, prices, jobs, or other website records. Define the deliverable before choosing a tool.
Our view: define the tool by the output it produces. If the deliverable is an IP-and-port list, call it a proxy scraper; if the deliverable is product rows or other website records, call it a web scraper that uses a proxy. Treating the two jobs as interchangeable is the fastest way to buy the wrong tool and misread a connectivity check as a data-collection result.
What Is a Proxy Scraper?
A proxy scraper is a tool that collects proxy server addresses, usually IP addresses and ports, from lists, websites, or APIs. Some proxy scrapers also check whether those endpoints respond. “Proxy scrapper” usually refers to this term with an extra “p.” A web scraper that uses a proxy is a different workflow: it collects website data through an intermediary server.
The distinction changes what you need to buy or build. If you need a list of proxy endpoints, you need a collector and potentially a checker. If you need product prices, job listings, or other website records, you need a web scraper; a proxy may be one part of its connection settings.
The Apify proxy-scraper repository illustrates the first meaning: its documented workflow gathers public proxies and optionally tests them against a chosen target. That documentation supports the distinction, not a claim that we ran or benchmarked its software.
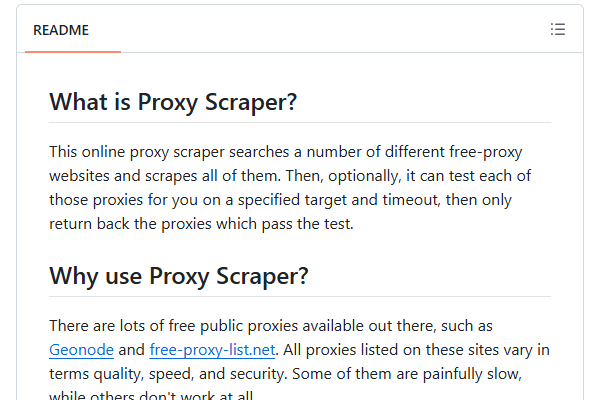
Screenshot: the project’s own README, captured 22 September 2026. This is documentation evidence, not an execution result.
Scraper vs. proxy vs. proxy scraper: 3 core terms
| Term | Main job | Typical output |
|---|---|---|
| Web scraper | Retrieve pages and extract selected fields | Product rows, prices, titles, or other structured records |
| Proxy server | Forward traffic between a client and a destination | A response relayed through a proxy endpoint |
| Proxy scraper | Collect proxy addresses from published sources | A list of proxy IP addresses and ports |
A proxy checker adds a separate test: it attempts a connection through an endpoint and records the result. A collector may include a checker, but collection alone does not verify reachability, safety, speed, or suitability for your destination.
Think about the deliverable before the infrastructure. An IP-and-port list will not turn a product page into a spreadsheet. Equally, a price scraper does not automatically supply a maintained proxy pool. Keeping these responsibilities separate makes errors easier to diagnose.
What does a proxy scraper actually collect?
A basic proxy list contains an address and a port. A useful evaluation record also tells you where an endpoint was found, which protocol was documented, and when any check occurred. Those extra fields prevent an old discovery from being mistaken for a current connection test.
| Field | Why it belongs in the record |
|---|---|
| Endpoint | Identifies the proxy address and port |
| Protocol | Distinguishes HTTP, HTTPS-related support, and SOCKS configurations |
| Source URL | Lets someone revisit the original listing |
| Discovery time | Records when the address was collected |
| Check target and time | Defines the context of a connection check |
| Result | Separates timeout, authentication error, denial, and valid content |
This is a proposed audit schema, not a dataset produced by this article. Do not populate it with invented success rates. A proxy that responded to an IP-check service yesterday may fail on a different destination today. A successful request also says nothing by itself about how the exit device was sourced.
If a list only supplies a country flag and an “online” badge, ask what was checked. Was the test a TCP connection, a successful HTTP response, or a correctly extracted record? Those are different outcomes, and a useful list should not collapse them into one green indicator.
Keep discovery and validation timestamps separate
When you refresh a proxy list, retain the original discovery record and write a separate validation result. Overwriting “last seen” with “last tested” makes it impossible to tell whether the collector found a new address or merely retried an old one. Store the test destination beside the result so a later reader can interpret what actually passed.
For a team handoff, include the endpoint format, permitted use, timeout setting, and reason an entry was rejected. Redact credentials before sharing the file. Do not pass a list of reachable endpoints to another team as a list of approved suppliers: connection checks and supplier review answer different questions. This small distinction makes the list useful for troubleshooting without overstating what the collection established.
How does a proxy server work with a web scraper?
In a proxy-assisted scraping workflow, the scraper connects through the configured endpoint. The proxy forwards the request to the destination and returns the response. The scraper then parses the response or renders the page and exports the fields you selected.
The destination generally sees the proxy’s outgoing IP as the network source. Other signals can still identify a session or application, including cookies, account activity, request headers, and browser behavior. Changing the outgoing IP does not remove those signals or guarantee anonymity.
Before choosing a provider, decide whether you need a stable session or independent page requests. A checkout-like navigation flow or a location-specific browsing session may depend on continuity. Switching IPs in the middle can produce inconsistent content or force a new session. See the IP rotation guide for the underlying concepts.
Residential, ISP, and datacenter labels describe different network offerings; they do not certify that a service can return your required data. The residential proxy explainer provides background, while an actual purchase decision still requires protocol, authentication, location, and session checks.
Why can a scraper still fail when it uses proxies?
A proxy only addresses part of the request path. A scraper can fail because the endpoint is unavailable, credentials are rejected, the destination limits traffic, a browser must render content, or the extraction rules no longer match the page.
| Symptom | First thing to check | What changing IP will not fix |
|---|---|---|
| Proxy authentication error | Authentication method and endpoint format | Incorrect credentials or an unsupported method |
| Timeout before a page loads | Endpoint availability and connection settings | A broken endpoint |
| Access-denied response | Permissions and the target’s access rules | Missing authorization |
| Rate-limit response | Request pacing and the target’s retry instructions | Permission to keep increasing traffic |
| Page loads but fields are empty | Rendering, selectors, and expected fields | An extraction rule pointing at the wrong element |
There is no universal safe number of requests per minute. Cloudflare’s rate-limiting documentation describes configurable rules for different traffic and application needs. A number from one site’s example should not become a general promise for all websites.
Keep retries bounded, record failures, and investigate their cause before changing several variables at once. If the destination rejects your access, review the permitted collection route. An official API, export, or approved data feed may be a better fit.
Use proxies in Octoparse: check compatibility first
Octoparse is a web data platform built around the Templates Gallery, visual authoring in Octoparse Desktop, and owned extraction infrastructure. Start with the data you want to collect, then decide whether the task needs additional proxy configuration. This keeps the extraction workflow separate from the choice of network provider.
Collect a repeatable price list without buying the wrong endpoint
For a price-monitoring task, define the product identifier, price, currency, page URL, and observation time first. Check the Templates Gallery before authoring a custom workflow. If the site requires a custom workflow, author it in Desktop and inspect a small local extraction before scaling it.
\r\n\r\nThe current proxy documentation makes an important distinction: your own proxies are for local runs; built-in proxies support local and Cloud use. It documents HTTP support for external proxies and says username/password proxies are unsupported. A provider advertising SOCKS5 does not by itself establish an Octoparse-compatible setup.
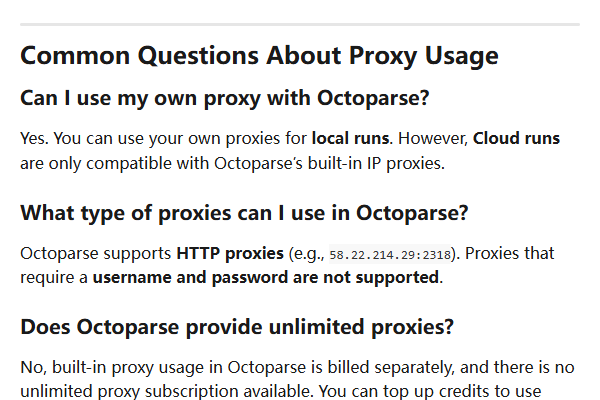
Screenshot: Octoparse Help Center, captured 22 September 2026. Recheck the documentation for your installed version before buying a plan.
The documentation also distinguishes the proxy setting used to sign in to Octoparse from the one used by an extraction task. A working login connection does not demonstrate that the task is using the same route. Configure and verify the task separately.
When evaluating a third-party endpoint, ask the supplier for the supported protocol, authentication method, address format, and intended runtime. Then verify a small, permitted workload and inspect the exported fields. This guide does not claim that a particular supplier’s account has passed that integration test.
Keep a before-and-after record with the same task and field requirements. If the page loads but the price field is still empty, inspect extraction rules instead of purchasing more IPs. If you need a fully managed delivery rather than operating the task, consider the separate Data Service.
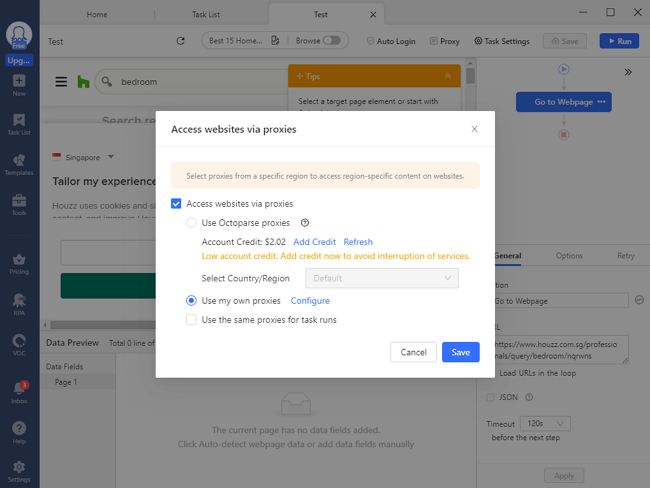
The existing article’s interface image is retained for continuity. The dated documentation screenshot above is the source for the current compatibility statement.
How should you evaluate a proxy provider?
Start with compatibility, then calculate cost against usable output. IP count is a poor substitute for a valid record: a large advertised pool cannot fix an unsupported authentication method, missing fields, or an unsuitable target policy.
Use this order for a small pilot:
- Choose a permitted target and write down the fields that must be present.
- Confirm protocol, authentication, runtime, and region requirements.
- Record the task version, sample scope, retry limit, and date.
- Separate connection success from a complete, valid exported record.
- Compare billed usage with accepted output and investigate errors before scaling.
The proxy provider comparison covers selection criteria and dated checks for brands including 922 proxy, 9Proxy, and ProxyJet. It belongs to the buying decision; this page owns the terminology and setup explanation.
Proxy scraper FAQ
- Is a proxy scraper the same as a web scraper that uses proxies?
No. A proxy scraper collects proxy addresses. A web scraper using proxies collects website data through those endpoints. A product can combine these functions, but its output and documentation should identify which one it performs.
- Does a free proxy list contain working proxies?
Not necessarily. Discovery is different from validation, and a connection result is specific to a target and time. Check provenance, protocol, authentication, and permission before relying on any endpoint. Do not infer safety from the fact that an address is publicly listed.
- Can I use 9 proxy or another provider with Octoparse Cloud?
Do not assume that an external provider is supported in Cloud. Check the documented runtime and authentication requirements. The supplier’s support for multiple protocols is only one part of compatibility; this article has not tested a paid account from that supplier.
- How much do Octoparse built-in proxies cost?
The official setup guide lists $3/GB, checked 22 September 2026. Proxy traffic is billed separately. Treat this as a dated documented price, not a guaranteed cost per page or per completed record.
- What does HTTP 429 mean when scraping through a proxy?
HTTP 429 means Too Many Requests. The response may include a Retry-After header. Reduce or pause requests and follow the destination’s instructions rather than treating rotation as permission to ignore the limit.
- Does using a proxy make scraping legal?
A proxy is a connection mechanism, not permission to collect or reuse data. Review the destination’s rules and applicable obligations for your project. The proxy-scraping legal guide discusses that separate assessment.